
Both 400G Ethernet and InfiniBand NDR deliver a nominal bandwidth of 400 Gb/s per port. However, identical port speeds do not guarantee identical performance in AI training clusters.
The differences extend beyond raw bandwidth. InfiniBand uses native RDMA transport and credit-based link-level flow control, while 400G Ethernet typically relies on RoCEv2 with appropriate congestion management and QoS configurations for high-performance GPU communication.
Hardware compatibility is another important consideration. Although both ecosystems use high-speed PAM4 signaling and may support similar optical form factors, their host interfaces, port configurations, and protocol requirements are not always interchangeable.
This guide compares 400G Ethernet vs InfiniBand NDR across performance, latency, congestion control, switching platforms, optical transceivers, cabling, and total cost of ownership. It also provides a practical RoCEv2 tuning checklist and a framework for choosing the right fabric for AI workloads.
400G Ethernet vs InfiniBand NDR: Same Line Rate, Same Fabric?
Not exactly. Both technologies offer 400 Gb/s connectivity, but their networking architectures and operational requirements differ.
InfiniBand NDR supports 400 Gb/s links using four 100G-class PAM4 electrical lanes, with forward error correction (FEC) to maintain signal integrity. Its architecture is designed for high-performance computing, low-latency communication, and native RDMA.
400GbE also uses PAM4 signaling, although the electrical lane configuration depends on the Ethernet interface generation and host implementation. Common implementations include 8×50G-class and 4×100G-class electrical interfaces.
For GPU networking, 400GbE commonly uses RDMA over Converged Ethernet version 2 (RoCEv2), which transports RDMA traffic over UDP/IP networks.
The primary differences are summarized below.
| Feature | InfiniBand NDR 400G | 400GbE with RoCEv2 |
| Nominal port bandwidth | 400 Gb/s | 400 Gb/s |
| RDMA transport | Native InfiniBand RDMA | RoCEv2 over UDP/IP |
| Flow control | Credit-based link-level flow control | Ethernet flow control and congestion management |
| Congestion management | InfiniBand congestion-control mechanisms | ECN, endpoint congestion control, and optionally PFC |
| Latency | Optimized for low-latency HPC communication | Depends on NIC, switch, topology, and configuration |
| Effective collective bandwidth | Workload- and topology-dependent | Workload- and topology-dependent |
| Typical optical form factors | OSFP, QSFP112 | OSFP, QSFP-DD, QSFP112 |
| Switch platforms | NVIDIA Quantum-2 | NVIDIA Spectrum-4, Broadcom-based platforms |
| Common use cases | AI training, HPC, large-scale RDMA clusters | AI training, inference, storage, and general data center networking |
The most important difference is not the nominal line rate. It is how each fabric manages communication, congestion, and packet delivery under demanding workloads.
One detail is particularly important when comparing InfiniBand NDR hardware.
A single NDR link operates at 400 Gb/s. NVIDIA Quantum-2 switches also support twin-port OSFP implementations that provide two independent 400G links through one physical module, for an aggregate capacity of 800 Gb/s.
These are two separate 400G connections rather than one native 800G NDR link.
Latency and Effective Bandwidth at 400G
Raw port bandwidth alone does not determine AI training performance.
Although 400G Ethernet and InfiniBand NDR provide the same nominal per-port bandwidth, their actual application performance depends on several factors:
- Network topology and switch-hop count
- GPU and server interconnect architecture
- RDMA transport and congestion-control configuration
- Message size and communication patterns
- Network oversubscription and competing traffic
- Software libraries, drivers, and firmware
InfiniBand is specifically optimized for low-latency HPC communication. Its transport architecture and link-level flow control help maintain predictable performance under demanding workloads.
RoCEv2 can also deliver high bandwidth and low latency over Ethernet, particularly when deployed with appropriate NICs, switches, and congestion management.
However, the performance difference between the two fabrics is not a fixed percentage.
For example, an AI cluster using 400G InfiniBand may outperform an equivalent RoCEv2 deployment under certain congestion conditions, while a well-designed Ethernet fabric may deliver competitive results for other workloads.
Understanding Effective AllReduce Bandwidth
AllReduce is a collective communication operation widely used in distributed AI training. It combines data across GPUs and distributes the resulting values to participating devices.
Its performance is influenced by both local GPU interconnects and the network connecting different servers.
When evaluating NCCL AllReduce results, it is important to distinguish between:
- Algorithm bandwidth (algbw): The effective bandwidth calculated from the data size and collective operation time.
- Bus bandwidth (busbw): A normalized bandwidth metric that accounts for the communication characteristics of the collective algorithm.
These metrics should not be confused with the physical throughput of a single 400G network port.
For reference, a 400 Gb/s connection provides a nominal bandwidth equivalent to 50 GB/s before accounting for relevant transmission and protocol overhead.
An eight-GPU server using NVLink or NVSwitch can report aggregate collective bandwidth far above 50 GB/s because much of the communication may occur within the server rather than across one external network connection.
Therefore, meaningful InfiniBand NDR vs Ethernet benchmarks should use comparable GPU systems, NIC configurations, network topologies, and workloads.
At larger cluster scales, tail latency and congestion become increasingly important because collective operations depend on communication among multiple participants.
Instead of relying on average latency alone, monitor P99 and P999 latency, collective completion time, and sustained bandwidth under representative workloads.
Lossless Transport: Credit-Based vs PFC/ECN
One of the most important architectural differences between InfiniBand and traditional RoCEv2 Ethernet fabrics is how they manage flow control and congestion.
InfiniBand: Credit-Based Flow Control
InfiniBand uses credit-based link-level flow control.
A transmitting device tracks the receive-buffer resources available at the next hop and sends data according to the available credits.
This mechanism is designed to prevent receiver-buffer overflow during normal operation and provides a foundation for lossless link-level communication.
Unlike traditional RoCEv2 Ethernet deployments, InfiniBand does not depend on Ethernet Priority Flow Control (PFC).
However, this does not mean InfiniBand requires no configuration.
Large InfiniBand fabrics still require appropriate subnet management, routing, QoS configuration, congestion management, and monitoring.
Hardware failures, transmission errors, or incorrect configurations can also affect reliability and performance.
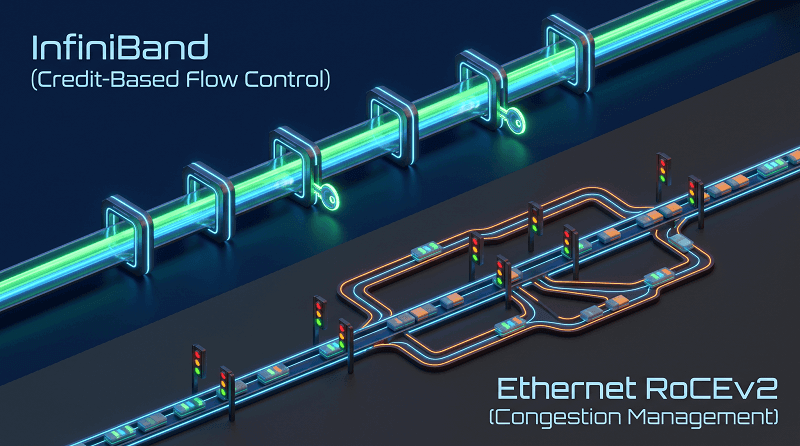
Ethernet: RoCEv2 Congestion Management
RoCEv2 enables RDMA communication over Ethernet and IP networks.
Because Ethernet does not inherently provide the same credit-based link-level flow control as InfiniBand, traditional lossless RoCEv2 deployments commonly combine several mechanisms:
- Priority Flow Control (PFC): Pauses selected traffic priorities when necessary to reduce packet loss caused by congestion.
- Explicit Congestion Notification (ECN): Marks packets to signal congestion before buffers overflow.
- DCQCN: A congestion-control mechanism supported by certain RoCE-capable NICs that adjusts transmission rates based on congestion feedback.
- QoS and traffic classification: Ensure consistent priority handling across NICs and switches.
These mechanisms perform different functions and must be configured appropriately for the hardware and network design.
Enabling PFC indiscriminately across all traffic classes can create unnecessary pause propagation, head-of-line blocking, and other performance problems.
Similarly, inappropriate ECN thresholds or inconsistent priority mappings can reduce throughput and increase tail latency.
A well-configured RoCEv2 fabric can achieve excellent performance, but its behavior must be validated under realistic traffic conditions.
The practical difference is that InfiniBand provides more of its flow-control behavior as part of the native fabric architecture, while conventional RoCEv2 deployments often require more explicit Ethernet configuration.
The 400G Hardware Behind Each Fabric
Selecting a 400G fabric involves more than choosing between two network protocols.
Switch architecture, NIC capabilities, supported transceiver form factors, and platform software all influence deployment flexibility and performance.
| Platform | Fabric | Role | Key capabilities |
| NVIDIA Quantum-2 | InfiniBand NDR | Switch | Up to 64×400G ports, 51.2 Tb/s aggregate bidirectional bandwidth |
| NVIDIA Spectrum-4 SN5600 | Ethernet | Switch | Up to 128×400GbE or 64×800GbE through supported port configurations |
| Broadcom Tomahawk 5 | Ethernet | Switch silicon | 51.2 Tb/s switching capacity |
| NVIDIA ConnectX-7 | InfiniBand / Ethernet | NIC / HCA | Selected VPI models support 400G and both protocols |
| NVIDIA BlueField-3 | Ethernet / InfiniBand variants | DPU | High-performance networking, acceleration, and infrastructure offload; capabilities vary by SKU |
ConnectX-7: InfiniBand and Ethernet Support
NVIDIA ConnectX-7 is particularly useful when evaluating the two networking ecosystems.
Certain ConnectX-7 VPI adapters support both InfiniBand and Ethernet operation, allowing organizations to evaluate different fabric architectures using compatible adapter hardware.
However, protocol support depends on the specific adapter model.
The operating mode is configured through supported firmware settings or management utilities such as NVIDIA mlxconfig. Connecting the adapter to a different switch does not automatically guarantee that the protocol mode will change correctly.
Before selecting ConnectX-7 hardware, confirm:
- Maximum supported port speed
- InfiniBand and Ethernet protocol support
- Port count and physical connector type
- Firmware and driver compatibility
- Supported optical transceivers and cable assemblies
NVIDIA’s ConnectX-7 specifications provide additional model-specific information.
Spectrum-X vs InfiniBand
NVIDIA Spectrum-X is an Ethernet networking platform designed for AI workloads.
It combines Spectrum Ethernet switching, compatible network adapters or DPUs, and an optimized networking software stack to support high-performance RoCE communication.
Quantum-2, by comparison, provides a native InfiniBand architecture.
For organizations considering NVIDIA hardware, Spectrum-X and Quantum-2 represent two different approaches to AI networking.
Broadcom-based Ethernet platforms provide additional hardware sourcing options for organizations that prioritize a multi-vendor networking ecosystem.
InfiniBand NDR deployments, particularly those using Quantum-2 switches, are more closely associated with NVIDIA’s integrated hardware and software ecosystem.
Where Form Factors Diverge at 400G
Optical module compatibility is one of the most important practical considerations when building a 400G network.
InfiniBand NDR and 400GbE may use similar high-speed electrical technologies, but their transceivers, host interfaces, and supported port configurations are not automatically interchangeable.
OSFP Twin-Port
Twin-port OSFP is widely used in NVIDIA Quantum-2 NDR switches and certain Spectrum-4 Ethernet platforms.
A twin-port OSFP implementation can support two independent 400G links through one physical module.
This provides an aggregate capacity of 800 Gb/s while maintaining separate logical connections.
It is particularly useful in high-density switching systems that require a large number of 400G ports.
QSFP-DD
QSFP-DD is widely used in 400GbE switching platforms.
The form factor provides an eight-lane electrical interface and supports a broad range of Ethernet optical transceivers.
However, QSFP-DD should not be treated as universally compatible with InfiniBand NDR equipment.
Compatibility depends on the switch or adapter’s physical cage, electrical interface, supported protocol, and transceiver specifications.
A QSFP-DD transceiver cannot be directly inserted into an OSFP or QSFP112 cage.
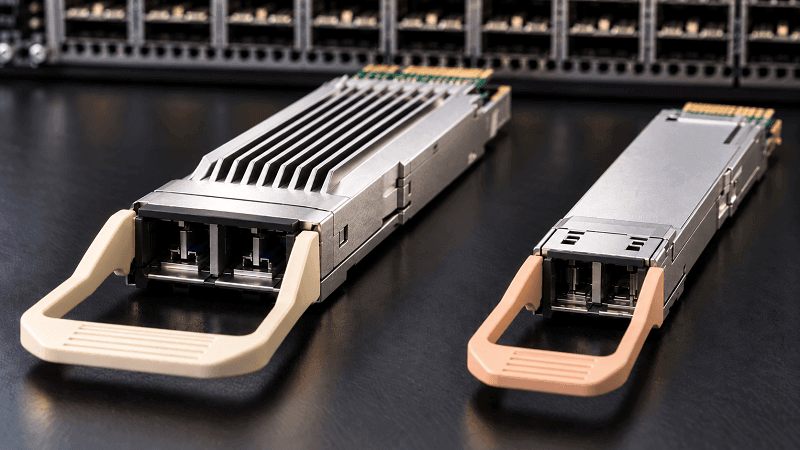
QSFP112
QSFP112 is a four-lane, 100G-class PAM4 form factor commonly used for 400G connectivity.
It is supported by selected high-performance adapters, including certain NVIDIA ConnectX-7 and BlueField-3 models.
QSFP112 products are available for different networking applications, but the form factor alone does not guarantee compatibility with both Ethernet and InfiniBand.
For more information about its electrical interface, applications, and compatibility considerations, read our QSFP112 Transceiver Guide.
Why Host Compatibility Matters
Although single-port and twin-port OSFP implementations may share the same physical dimensions, their internal port configurations and electrical lane mappings can differ.
A cable or transceiver designed for one host configuration may not operate correctly in another.
Incompatible combinations can result in link failures, unavailable ports, unsupported breakout modes, or other connection problems.
Before purchasing 400G transceivers and cables, verify:
- Host device model and port specifications
- Physical form factor and cage compatibility
- Supported electrical lane configuration
- Protocol and firmware requirements
- Optical connector type and fiber polarity
- Supported breakout or multi-port configurations
On InfiniBand systems, tools such as ibstat can help verify the negotiated link state and speed.
Cabling and Optics: The Biggest Line Item
Transceivers and cable assemblies are usually the largest single line item in a 400G fabric BOM. That surprises people who assume the switches dominate the budget.
The reach requirements drive the cost.
| Type | Reach | Typical use | Indicative 2026 price per end |
| Passive copper DAC | 1–3 m | In-rack, switch to NIC | $280–450 |
| Active optical cable (AOC) | 3–30 m | Adjacent racks | $1,500–2,800 |
| OSFP SR4 multimode | ~50 m | Multimode structured cabling | $1,800–2,400 |
| OSFP DR4 single-mode | ~500 m | Single-mode runs | $2,400–3,200 |
| OSFP FR4 single-mode | ~2 km | Longer campus runs | $3,500–5,000 |
| Twin-port AOC (800G aggregate) | 3–30 m | Two 400G links per module | $2,800–4,500 |
Two details trip up deployments more than anything else here, and both are specific to NDR optical links. First, the MPO connectors must be APC polish. UPC causes link flaps, and the symptom looks like a bad optic rather than a bad polish. Second, fiber polarity and connector gender have to be correct for the cassette or trunk you’re using, or you’ll spend a day chasing links that won’t come up.
NVIDIA’s LinkX cables and transceivers guide is the reference for the passive layer on both fabrics.
For the form factor comparison in more depth, our article on 400G QSFP-DD vs OSFP vs QSFP56 walks through cage compatibility and breakout options. And if you’re building the passive layer at the same time, the InfiniBand DAC and AOC cables guide covers reach and type selection by generation.
Need the optics side sorted before the switches land? FiberMall supplies 400G modules for both fabrics, including 400G NDR InfiniBand transceivers and 400GbE QSFP-DD alternatives. Request a quote and we’ll spec the BOM against your switch platform.
Making 400GbE RoCEv2 Perform
If you choose Ethernet, this is the section that decides whether you get 90% of InfiniBand or 30% of it. The difference is configuration.
Work through this before you trust a single benchmark:
1. Restrict PFC to the RDMA priority class only. Global PFC is the most common misconfiguration and the cause of pause storms.
2. Raise ECN thresholds from their web defaults. Values in the 500KB–1MB range suit all-reduce traffic; data center defaults are usually too aggressive.
3. Enable DCQCN end to end and confirm the NIC, driver, and switch all agree on it.
4. Turn on adaptive routing. Static routing causes out-of-order delivery that stalls AllReduce.
5. Align QoS and DSCP mapping across NIC, driver, and switch port.
6. Validate on P99 and P999 all-reduce latency. Averages hide the tail that costs you training time.
7. Inject a storage burst and confirm tail latency holds under incast. A fabric that’s lossless when idle proves nothing.
A well-tuned 512-GPU cluster should land above 90% bus-bandwidth utilization with P99 all-reduce latency under 2.5 microseconds. If you’re well below that, the fabric isn’t the problem. The configuration is.
Budget about two weeks of tuning effort for a first 400GbE deployment. Teams that have done it before move faster, but the first one is a project, not a checkbox.
Cost and TCO: 400G Ethernet vs InfiniBand
Ethernet wins on acquisition cost, and it isn’t close. Per-port pricing on 400GbE runs roughly 30–50% below InfiniBand once you include switches and optics.
InfiniBand wins on engineering time. You spend less configuring it and less troubleshooting it, because losslessness is a property of the fabric rather than a setting you own.
Both of these can be true at the same time, and the public evidence shows it. Meta reportedly found that InfiniBand’s roughly 15% performance advantage didn’t justify a 2.3× TCO premium across a fleet approaching 600,000 GPUs. OpenAI, working with the same two options, credited InfiniBand’s congestion control with enabling training that ran about 40% faster than their earlier Ethernet attempts.
Read those two results together and the lesson isn’t that one vendor was right. It’s that scale changes the answer. At Meta’s scale, the per-port premium compounds into a number that overwhelms the performance gain. For a team whose first Ethernet fabric was undertuned, the performance gap dominated everything.
Third-party optics shift this math further. Buying MSA-compatible 400G modules instead of OEM-branded parts changes a large fraction of the BOM, and the modules are built to the same standards.
Ultra Ethernet 1.0: Does It Close the Gap?
Ultra Ethernet Consortium (UEC) 1.0 arrived in June 2025, with a 1.0.1 update that September. It’s a Linux Foundation project backed by AMD, Arista, Broadcom, Cisco, HPE, Intel, Meta, Microsoft, and Oracle.
The core change is a new transport layer, Ultra Ethernet Transport, that replaces Ethernet’s older upper layers while keeping commodity Ethernet underneath. It brings packet spraying across all available paths, multi-path RDMA with out-of-order delivery reassembled at the NIC, selective retransmission of only lost packets, and modern congestion control that doesn’t depend on PFC for correctness. PFC becomes a backstop rather than a requirement.
That last point is the one to watch. If PFC stops being load-bearing, the dominant failure mode of 400GbE clusters stops being the dominant failure mode.
The honest caveat is timing. UEC 1.0 shares hardware with RoCEv2, and compatible products were still emerging through 2025 and 2026. The 2026 work is focused on programmable congestion management, small-message performance, and in-network collectives.
Treat all of it as roadmap, not shipping spec. Read the specification directly at the Ultra Ethernet Consortium if you want the primary source.
400G Ethernet vs InfiniBand: Which Fabric Fits Your Cluster?
Here’s the decision framework, stated plainly.
| Your situation | Fabric to pick | Why |
| 64+ GPUs pretraining one large model | InfiniBand NDR | Lossless by design, lowest tail latency |
| DGX or HGX reference architecture | InfiniBand NDR | Ships certified, nothing to tune |
| Tail latency is contractually critical | InfiniBand NDR | Sub-microsecond switch hops |
| No appetite for owning PFC and ECN | InfiniBand NDR | Losslessness is a fabric property |
| 32 GPUs or fewer | 400GbE + RoCEv2 | Cheaper, and the gap is small at this scale |
| Mostly inference or fine-tuning | 400GbE + RoCEv2 | Collective-heavy training isn’t the bottleneck |
| Models under about 70B parameters | 400GbE + RoCEv2 | Bandwidth demand stays moderate |
| Deep IP networking expertise in-house | 400GbE + RoCEv2 | One fabric for compute, storage, and management |
| Training plane plus storage and management | Hybrid | Optimize each network for its own traffic |
Choose a hybrid when you want the best of both. The pattern that’s now common runs InfiniBand for the training plane and Ethernet for storage, inference, and management. Each network gets optimized for what it actually carries instead of compromising.
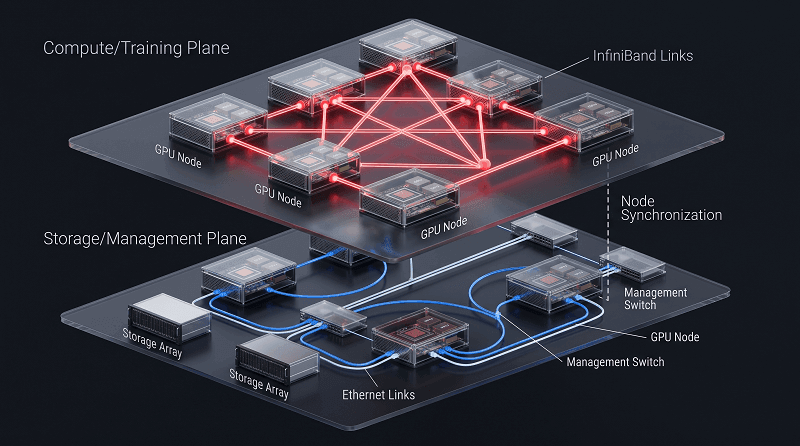
Scale should drive this decision more than preference. Ethernet has overtaken InfiniBand in AI back-end switching, reaching roughly two-thirds of that market by early 2026, while InfiniBand remains the tight-latency default for the largest training builds. Both outcomes make sense given how differently the two fabrics behave at scale.
For the broader ecosystem comparison, our InfiniBand vs Ethernet article goes wider on operations and cloud availability. If you’re weighing RoCEv2 against a native fabric at the protocol level, the InfiniBand vs RoCEv2 comparison digs into the transport differences.
FAQ
Is 400G Ethernet as fast as InfiniBand NDR?
Both provide 400 Gb/s nominal port bandwidth. However, actual RDMA and AI workload performance depends on topology, congestion management, hardware, and configuration. Neither fabric has a universally fixed performance advantage.
Can 400G Ethernet replace InfiniBand for AI training?
Yes. Properly designed 400GbE RoCEv2 networks can support large-scale AI training. The best choice depends on collective communication requirements, performance targets, operational expertise, and deployment costs.
Does ConnectX-7 work with both InfiniBand and Ethernet?
Certain ConnectX-7 VPI models support both protocols. The operating mode must be configured appropriately through supported firmware settings or management tools, and capabilities vary by SKU.
What cable do I need for NDR 400G?
For short links, compatible DAC or AOC assemblies may be suitable. Longer links typically use optical transceivers such as SR4 or DR4. Verify the host form factor, module specifications, connector type, and transmission distance before purchasing.
Can I use QSFP-DD transceivers with InfiniBand?
QSFP-DD is primarily associated with Ethernet applications and cannot be physically inserted into OSFP or QSFP112 cages. For NDR deployments, select transceivers explicitly supported by the InfiniBand host platform and protocol.
How much does a 400G fabric cost per port?
Cost varies by switch, adapter, optical connectivity, topology, and supplier. Ethernet may offer more hardware sourcing options, but a meaningful comparison requires a complete BOM rather than a universal per-port price assumption.
Is InfiniBand NDR overkill for a 16-GPU cluster?
Not necessarily. A 16-GPU cluster may perform well with either fabric. InfiniBand can be justified for communication-intensive workloads, while Ethernet may offer a cost-effective alternative when supported by the application and network design.
Conclusion
The 400G Ethernet vs InfiniBand decision comes down to a few things that actually move the outcome.
Both fabrics deliver the same line rate, so line rate shouldn’t drive your choice. NDR 400G gives you lossless transport without configuration and roughly 15–20% better throughput at large scale. 400GbE costs 30–50% less per port and reaches 85–95% of InfiniBand’s performance, provided you tune PFC, ECN, and DCQCN properly and keep owning them.
Then there’s the part that has nothing to do with performance. At 400G the form factors split, and a twin-port OSFP cable in a single-port cage will quietly halve your bandwidth. Check negotiated rates, not labels.
For most teams the answer isn’t absolute. Match the fabric to your cluster size and workload, and consider running InfiniBand and Ethernet side by side rather than forcing one to do everything.
Not sure which 400G optics your fabric needs? Contact our networking experts with your switch platform and reach requirements. We’ll spec NDR OSFP, QSFP112, or 400G QSFP-DD to match, and you can compare the BOM before you commit to either fabric.
Related Products:
-
 FiberMall QSFP112-400G-VR4 Compatible 400G QSFP112 VR4 PAM4 850nm 50m MTP/MPO-12 OM4 FEC Optical Transceiver Module
$385.00
-
LQSFP112-400G-FR4 400G LPO QSFP112 FR4 PAM4 CWDM 2km Duplex LC SMF FEC Optical Transceiver Module
$1350.00
-
LQSFP112-400G-DR4 400G LPO QSFP112 DR4 PAM4 1310nm 500m MTP/MPO-12 with KP4 FEC Optical Transceiver Module
$1200.00
-
LQSFP112-400G-SR4 400G LPO QSFP112 SR4 PAM4 850nm 50m MTP/MPO-12 OM3 FEC Optical Transceiver Module
$800.00
-
QSFP112-400G-LR4 400G QSFP112 LR4 PAM4 CWDM 10km Duplex LC SMF FEC Optical Transceiver Module
$1000.00
-
QSFP112-400G-FR4 400G QSFP112 FR4 PAM4 CWDM 2km Duplex LC SMF FEC Optical Transceiver Module
$600.00
-
QSFP112-400G-FR1 4x100G QSFP112 FR1 PAM4 1310nm 2km MTP/MPO-12 SMF FEC Optical Transceiver Module
$800.00
-
QSFP112-400G-DR4 400G QSFP112 DR4 PAM4 1310nm 500m MTP/MPO-12 with KP4 FEC Optical Transceiver Module
$500.00
-
QSFP112-400G-SR4 400G QSFP112 SR4 PAM4 850nm 100m MTP/MPO-12 OM3 FEC Optical Transceiver Module
$400.00
-
OSFP-400G-SR8 400G SR8 OSFP PAM4 850nm MTP/MPO-16 100m OM3 MMF FEC Optical Transceiver Module
$299.00
-
OSFP-400G-DR4 400G OSFP DR4 PAM4 1310nm MTP/MPO-12 500m SMF FEC Optical Transceiver Module
$800.00
-
OSFP-400G-FR4 400G FR4 OSFP PAM4 CWDM4 2km LC SMF FEC Optical Transceiver Module
$900.00
-
OSFP-400G-PSM8 400G PSM8 OSFP PAM4 1550nm MTP/MPO-16 300m SMF FEC Optical Transceiver Module
$800.00
-
OSFP-2x200G-FR4 2x 200G OSFP FR4 PAM4 2x CWDM4 CS 2km SMF FEC Optical Transceiver Module
$1500.00
-
OSFP-400G-LR4 400G LR4 OSFP PAM4 CWDM4 LC 10km SMF Optical Transceiver Module
$1199.00
-
OSFP-400G-DR4+ 400G OSFP DR4+ 1310nm MPO-12 2km SMF Optical Transceiver Module
$850.00